

Hugging Face, a leading AI startup has unveiled a new benchmark for testing these models. Dubbed Open Medical-LLM, this initiative is a collaborative effort between Hugging Face, Open Life Science AI, a non-profit organization, and the University of Edinburgh’s Natural Language Processing Group.
New: Open Medical LLM Leaderboard! 🩺
In basic chatbots, errors are annoyances.
In medical LLMs, errors can have life-threatening consequences 🩸It's therefore vital to benchmark/follow advances in medical LLMs before thinking about deployment.
Blog: https://t.co/pddLtkmhsz
— Clémentine Fourrier 🍊 (@clefourrier) April 18, 2024
The primary purpose of Open Medical-LLM is to establish a standardized approach to evaluating the performance of generative AI models on a range of medical tasks and questions. This is critical because, unlike basic chatbots, where errors are inconveniences, mistakes made by medical AI models can have serious consequences.
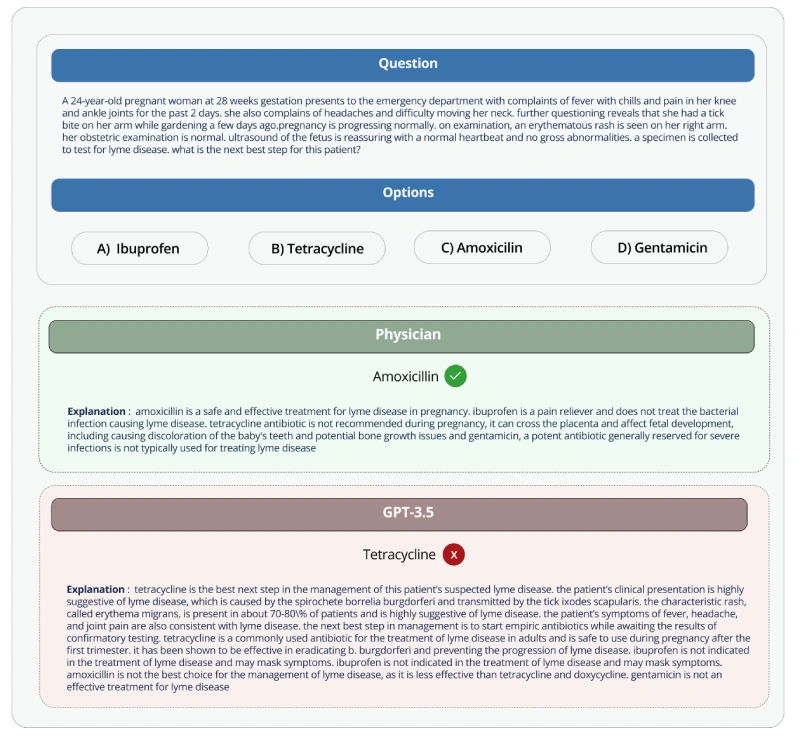
Source: Hugging Face
The benchmark itself consists of a variety of challenges designed to assess a model’s competency in medical reasoning and understanding. These challenges range from multiple-choice questions to open ended, requiring the AI to draw on information from real-world medical resources like licensing exams and college-level biology tests.
Hugging Face emphasizes that Open Medical-LLM empowers researchers and healthcare professionals to pinpoint both the strengths and weaknesses of different AI approaches. This information is vital for driving further advancements in the field and ultimately contributing to improved patient care and outcomes.
The new benchmark positions itself as a “robust assessment” tool for generative AI models specifically designed for healthcare applications. With the increasing presence of AI in healthcare settings, Open Medical-LLM serves as a crucial step towards ensuring the responsible development and deployment of these powerful tools.
